Rodrigo Viana
QA Associate Specialist at Axians Low-Code, with more than 15 years of experience in software testing across public sector projects, financial institutions, and private companies. He is ISTQB® certified in Test Automation (CTAL-TAE) and Security Testing (CTAL-ST), as well as at Foundation Level (CTFL).
Throughout his career, he has specialised in functional test automation (Selenium, Appium, Playwright, Katalon, UiPath), performance testing, and TestOps, with extensive experience in the OutSystems ecosystem. More recently, he has focused on applying generative AI to software testing, including test data generation, autonomous execution, and response evaluation.
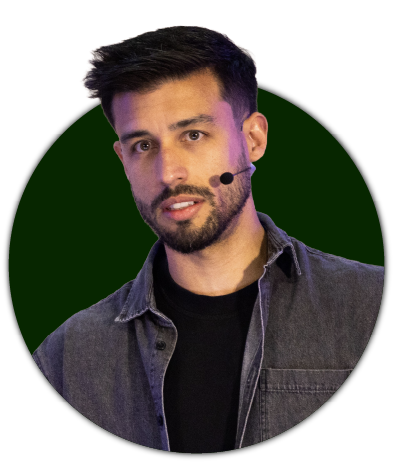
Rodrigo Viana
QA Associate Specialist at Axians Low-Code, with more than 15 years of experience in software testing across public sector projects, financial institutions, and private companies. He is ISTQB® certified in Test Automation (CTAL-TAE) and Security Testing (CTAL-ST), as well as at Foundation Level (CTFL).
Throughout his career, he has specialised in functional test automation (Selenium, Appium, Playwright, Katalon, UiPath), performance testing, and TestOps, with extensive experience in the OutSystems ecosystem. More recently, he has focused on applying generative AI to software testing, including test data generation, autonomous execution, and response evaluation.
CALENDAR
Call for Speakers
27 October
When “AI as a Judge” Isn’t Enough: Testing the Quality of an LLM Chatbot, from Functional Testing to Red Teaming
LLM-based chatbots are becoming increasingly common, but testing them presents a new challenge: their responses are non-deterministic, and traditional QA methods are not enough. This presentation will share a real-world case from Axians for IPDJ (Portuguese Institute of Sport and Youth): ensuring the quality of Appy, Apptiva’s chatbot, which uses an LLM to generate its responses.
We started by adapting DeepEval, a tool that uses the “AI as a Judge” approach. We quickly realised that its results — a simple count of passed and failed test cases against a predefined threshold — were not enough to guarantee quality. We therefore built our own testing layer, structured around several dimensions: functional testing, where we used AI to generate test data and validate whether the chatbot responded consistently to FAQs and their natural variations; security testing, to ensure that internal and user information was not exposed and that no health or medication recommendations were provided; and red team testing, focused on prompt injection and code injection.
To make the results actionable, we used generative AI to create a visual report that allows us to compare execution history and analyse regressions and improvements with each change to the model, base prompt, or FAQ content.
We conclude with what we consider to be the key takeaway: QA professionals need to master technical concepts such as “AI as a Judge” and combine them with their quality expertise to successfully test the new generation of LLM-based applications.
Calendar
Call for Speakers
27 October
Quando o "AI as a Judge"
Não Basta: Testar a Qualidade de um Chatbot com LLM,
do Funcional ao Red Team
LLM-based chatbots are becoming increasingly common, but testing them presents a new challenge: their responses are non-deterministic, and traditional QA methods are not enough. This presentation will share a real-world case from Axians for IPDJ (Portuguese Institute of Sport and Youth): ensuring the quality of Appy, Apptiva’s chatbot, which uses an LLM to generate its responses.
We started by adapting DeepEval, a tool that uses the “AI as a Judge” approach. We quickly realised that its results — a simple count of passed and failed test cases against a predefined threshold — were not enough to guarantee quality. We therefore built our own testing layer, structured around several dimensions: functional testing, where we used AI to generate test data and validate whether the chatbot responded consistently to FAQs and their natural variations; security testing, to ensure that internal and user information was not exposed and that no health or medication recommendations were provided; and red team testing, focused on prompt injection and code injection.
To make the results actionable, we used generative AI to create a visual report that allows us to compare execution history and analyse regressions and improvements with each change to the model, base prompt, or FAQ content.
We conclude with what we consider to be the key takeaway: QA professionals need to master technical concepts such as “AI as a Judge” and combine them with their quality expertise to successfully test the new generation of LLM-based applications.